Mutations / Anchored Plug-in MoE
MoE and LoRA.
One frozen LLM.
A Python research framework for Mixture-of-Experts routing, LoRA adapters, and modular language-model specialization. Train independent specialists while preserving an exact base-model fallback.
02 / Architecture
One stable base.
Mutations on demand.
Route tokens through packaged Qwen3 experts, select prompt-level LoRA adapters, or deploy Needle response branches. Each path keeps an explicit frozen-model fallback.
03 / Validated baseline
From exact fallback
to routed specialization.
The framework validates dense-equivalent conversion and a complete packaged anchored top-1 lifecycle. Advanced routes remain explicit composable or research paths until their model-level lifecycle is complete.
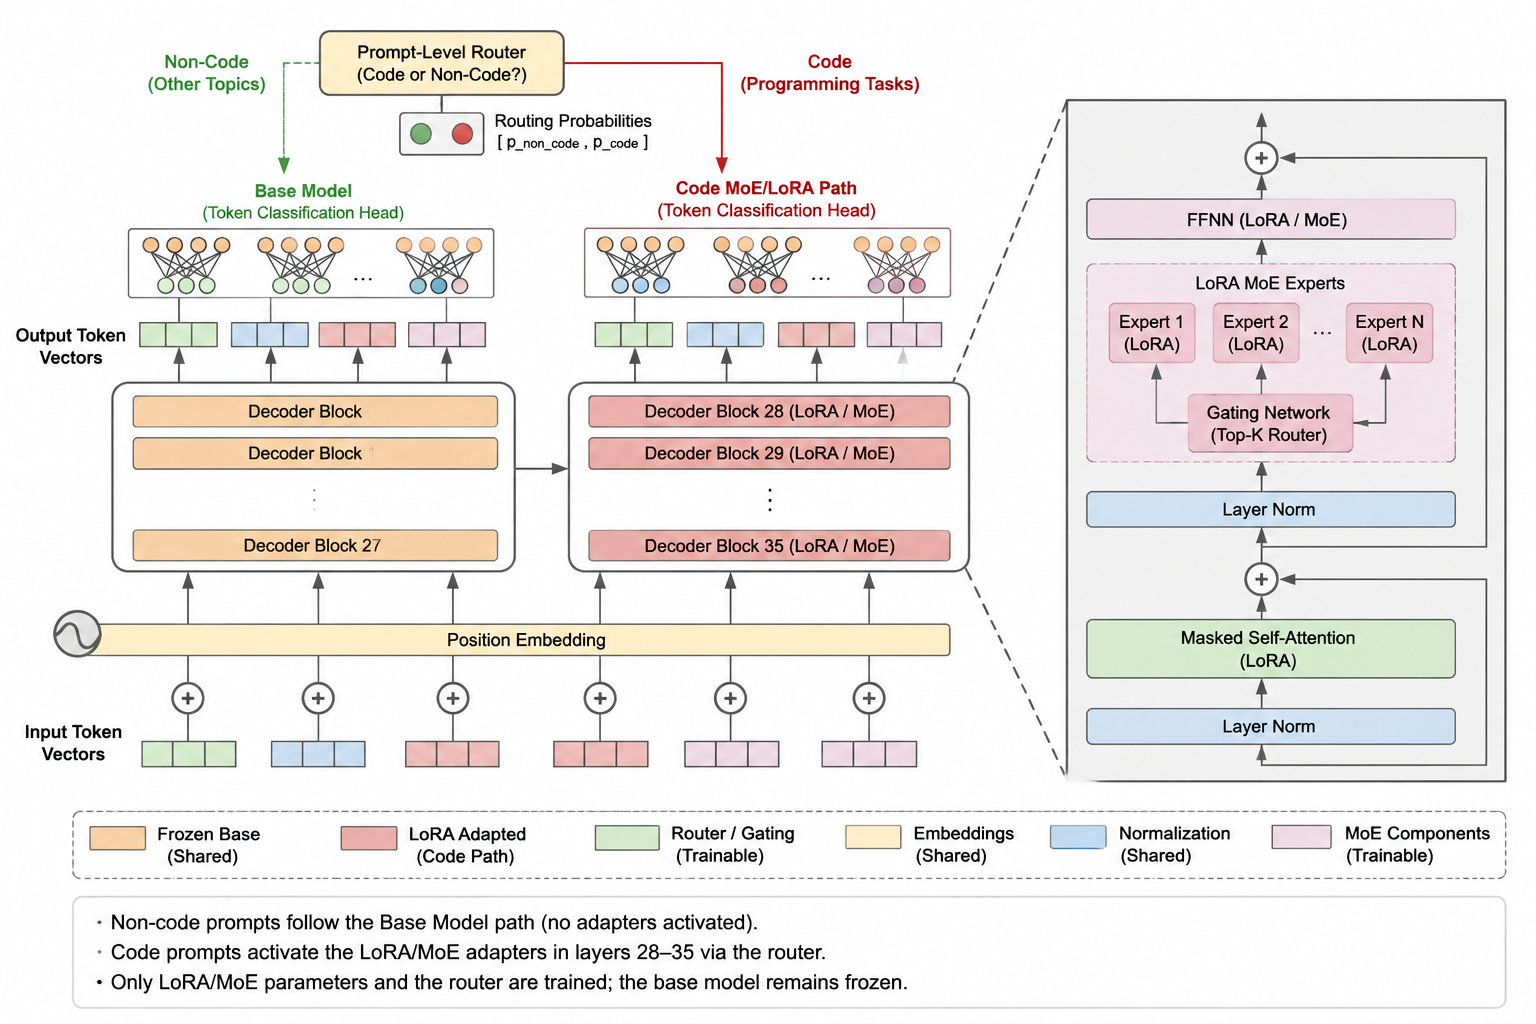 Architecture / full view ↗
- Base invariant
- Exact anchor fallback
- Lifecycle
- Install / remove / reload
- Integrated route
- Anchored top-1
- Advanced routes
- Composable primitives
04 / Read and inspect
An open research
scaffold.
The repository contains the framework paper, package-aligned guides, verified examples, and runnable training and evaluation notebooks.
Definitions, runtime protocol, mutation lifecycle, and the research program.
Open PDF ↗D / 18 guidesMoE and LoRA guidesQwen3 conversion, expert training, routing policies, and Needle/WASM deployment.
Browse docs →G / SourceGitHub repositoryInspect the Python package, tests, examples, notebooks, and project history.
View GitHub ↗